
Welcome to SGLang-Omni#
Serve speech and multimodal models with SGLang-Omni.
Speech & Multimodal Models. Transcribe audio, generate speech, and serve models that accept audio, images, and video through OpenAI-compatible APIs.
Streaming & Realtime. Stream transcripts and speech as they are generated. Use realtime sessions for live audio input and interactive voice applications.
Multi-stage Runtime. Run preprocessing, inference, and audio generation as stages with independent scheduling. The runtime is built on SGLang.
Hardware Support. Choose the installation guide for your hardware: CUDA, Apple Silicon, Ascend NPU, Intel XPU, Intel CPU, or MUSA. Model support varies by platform.
Get Started#
Quickstart — Start a model server and transcribe one audio clip.
Installation — Choose an installation method for your hardware.
Examples — Stream a transcript, generate speech, or send an audio chat request.
Browse supported models under Cookbook in the sidebar.
News and latest blogs#
Scroll sideways for more updates.
 Voxt 2.0.3: Open-source voice input for Mac
 OpenRSI × SGLang-Omni: Scaling RSI for AI Infra
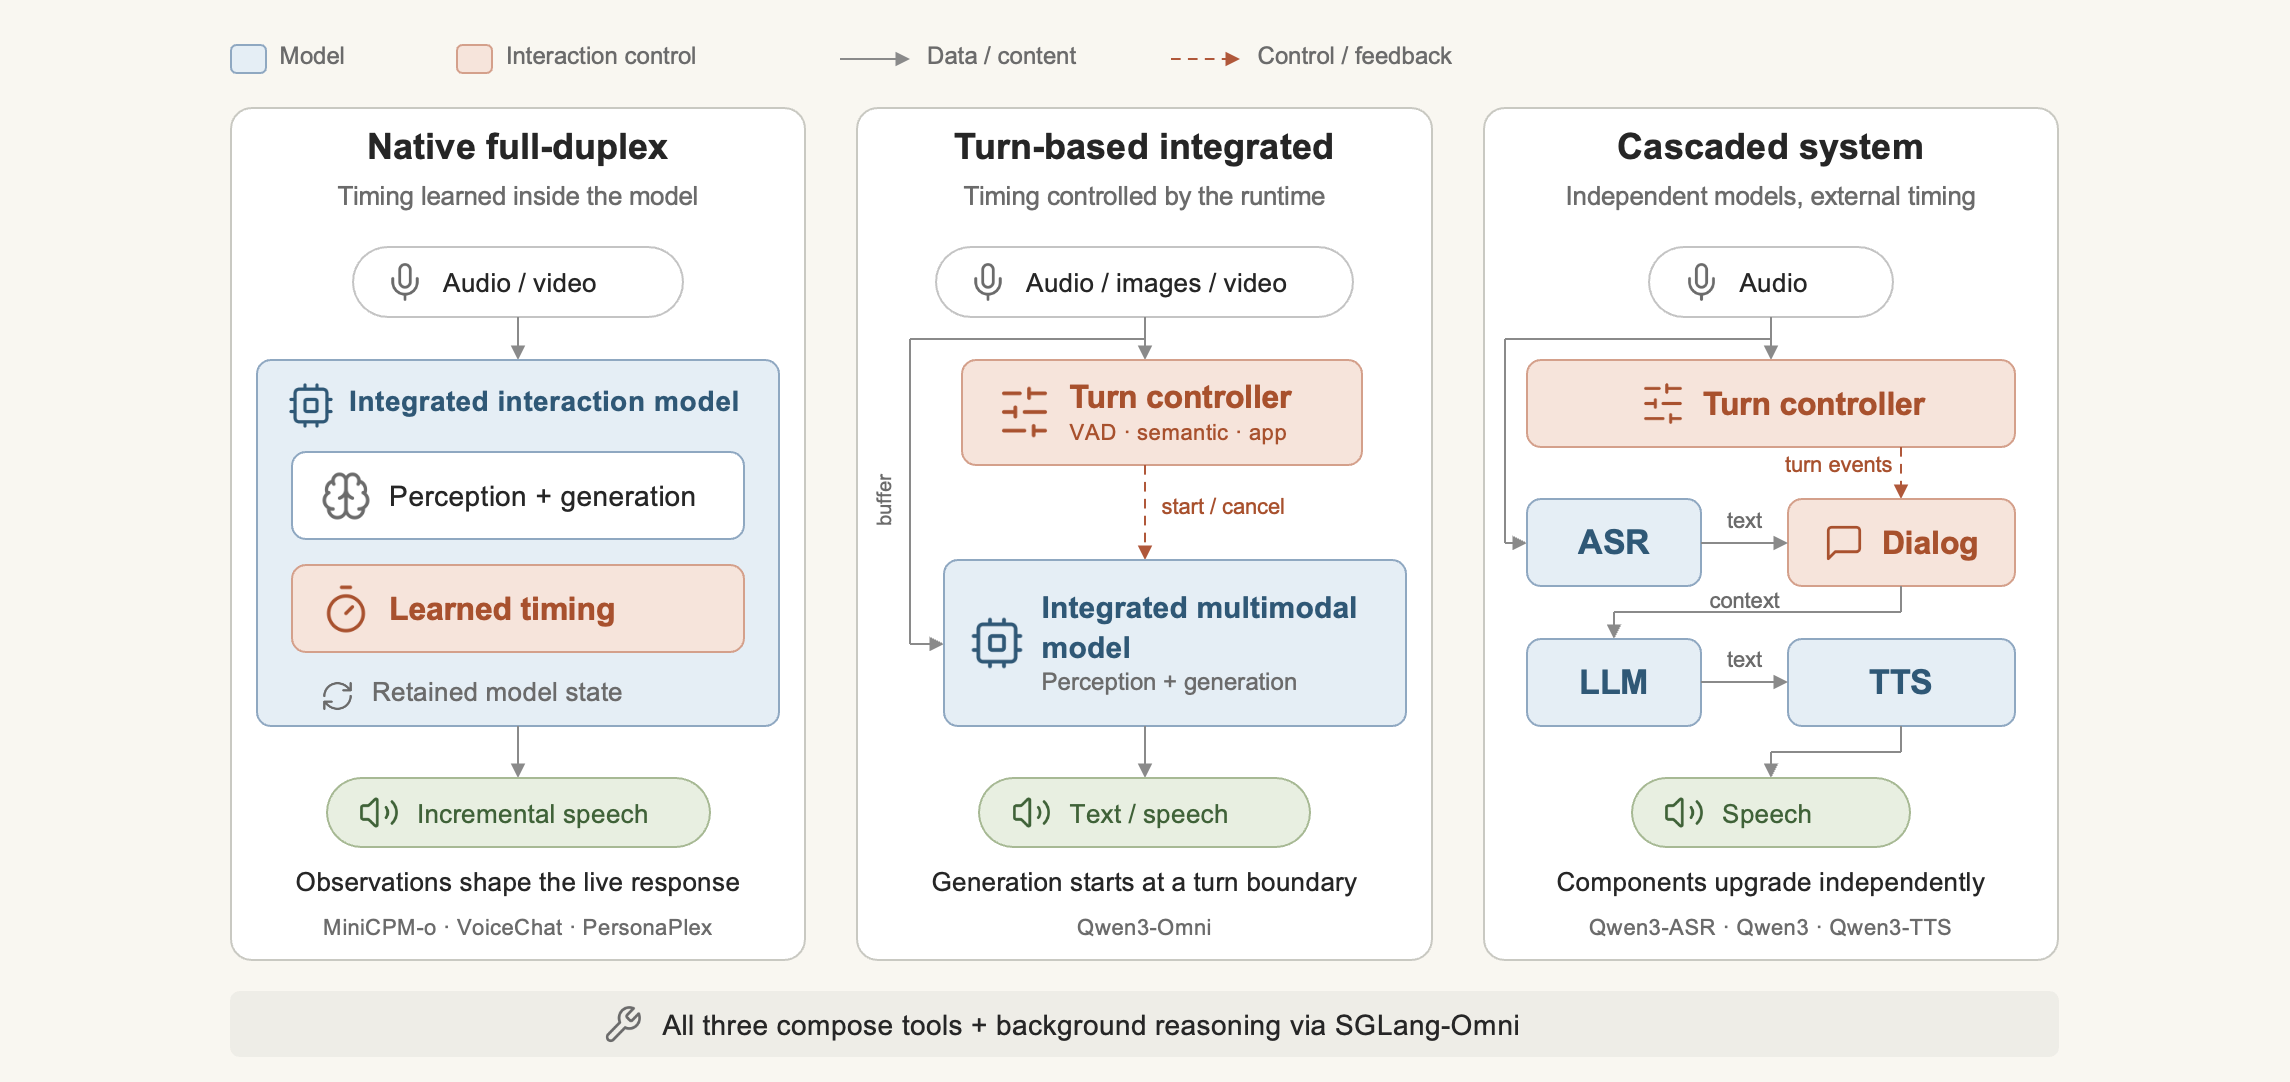 A unified runtime for full-duplex interaction
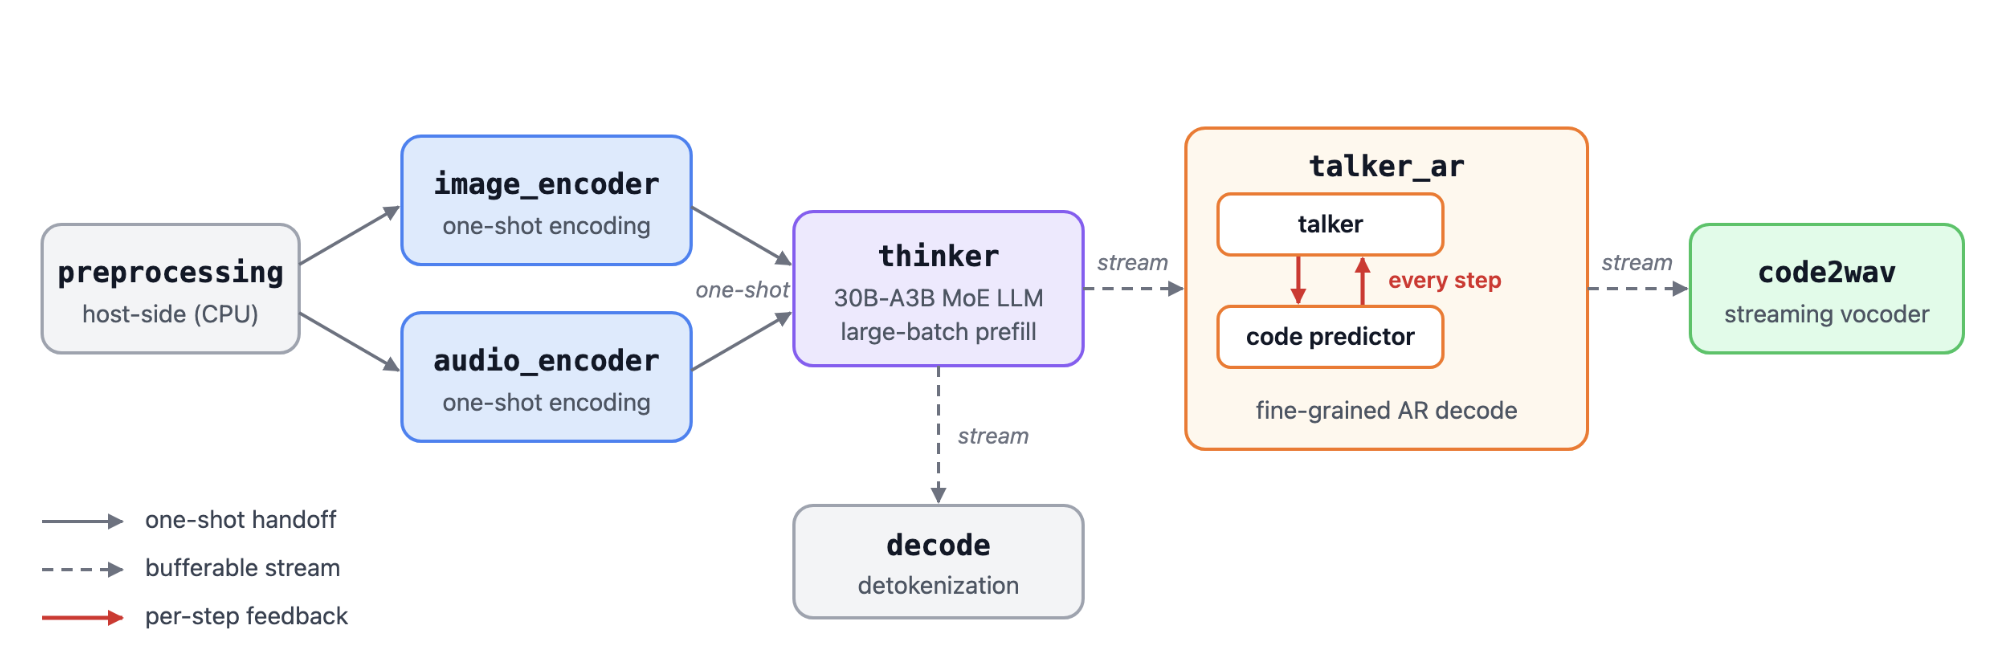 Serving multi-stage omni models with SPG
 Fish Audio Drama 3 launches with Omni support
Community & Resources#
SGLang Slack — Ask questions and discuss development.
GitHub and Developer Reference — Find the source and contribution resources.